This note preserves the original context of the Facebook post. Some tools, interfaces, and external links may have changed.
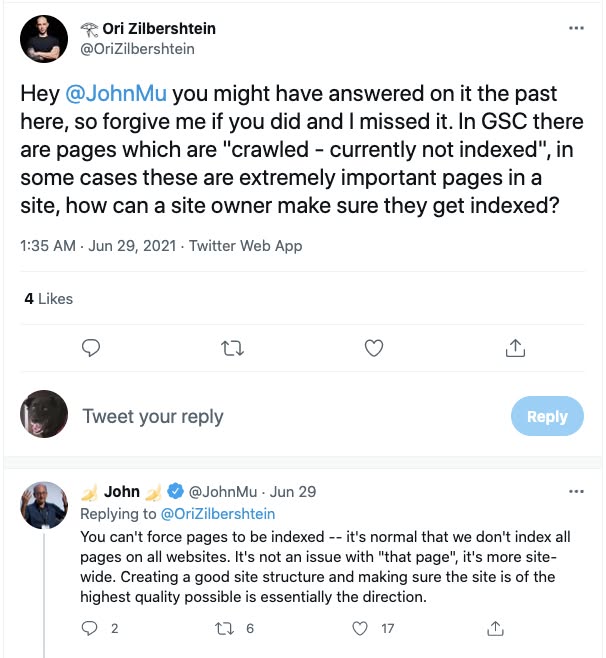
When encountering “Crawled, but not yet indexed”, the gut reaction is usually to submit the same URL over and over again.
This 2021 post serves as a reminder that the problem doesn’t have to be just with that page itself, but can also be with the entire website.
The original case mentioned that a certain website had been hacked, resulting in a large number of implanted pages.
Therefore, the post proposes a reasonable investigation direction: in addition to checking the target page, you should also check whether the website has a large number of abnormal pages, blank pages, spam external links, or traces of black hat operations.
The point here is not to claim that a certain factor will definitely cause non-indexing, but to remind SEO troubleshooting not to just focus on a single URL.
Website structure, content quality, technical errors and security incidents can all contribute to broader problems.
This is a historical note that preserves the context of the discussion at that time.
Search engine reporting and indexing systems will continue to change, and actual diagnosis should still be based on the current official documents and Search Console data.
Links mentioned in the original post
Related reading
How Search Engines Work: Crawling
Crawling is the first step in search. A crawler starts with a URL, visits it, discovers more URLs, and repeats the cycle. The concept sounds simple, but it contains many important SEO details.
An Introduction to Passage Retrieval
Google's passage retrieval system was expected to affect about 7% of search results as it expanded to searches in every language worldwide. What changed, and how should SEOs respond? Read on for a closer look.
SEO Newsletter Issue 64 – 2022.09.01–2022.09.15
This issue has quite a bit to read. I especially recommend the pieces on SEO interview questions, research into infinite scrolling, and the growing number of webpages going unindexed; each one gave me a different perspective. A new core algorithm update also arrived just before my deadline, and I hope everyone makes it through this round smoothly!
Can search engines really see the content generated by JavaScript?
Saves a practical note on using the Search Console URL inspection tool to confirm whether JavaScript content is rendered, and links back to the basic article on search engine crawling and indexing.
Search Console search statistics: What pages is Google crawling recently?
Organizes discovery and reorganization concepts in Search Console search statistics, linking crawler behavior back to sitemaps, duplicate URLs, and troubleshooting of site-embedded pages.
Blank category page: noindex, soft 404 and page change signal
Starting from the discussion of blank category pages in e-commerce, we sort out the differences between noindex and soft 404, and how changes in content, internal links, and products can serve as signals for re-examination.